Principle of clustering
Thresholding applies well on a grayscale image, for which it is easy to define a threshold from the modes of the histogram. However, this approach cannot be applied on a color or multiband image because no histogram can be computed.
Each pixel in a -band image can be represented by a point in a -dimensional space. By doing so, pixels with similar colors form groups in the space, as illustrated in Figure 1.
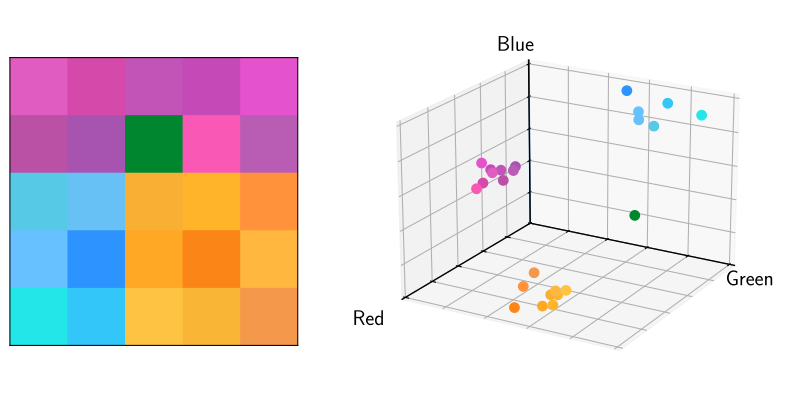
Figure 1:Pixels of a color image in a -dimensional space ().
Clustering methods consists in defining groups of pixels. Therefore, all the pixels in the same group define a class in the segmented image.
The K-means algorithm
A classical clustering method for image segmentation is the K-means algorithm (French: K-moyennes) [Steinhaus 1957, MacQueen 1967]. This is an iterative method that affects every point in the space to a group (called cluster). The number of clusters is chosen by the user.
We also define centroids as the center of a cluster: its coordinates are the mean of the point coordinates belonging to the cluster.
The K-means algorithm is given below.
Application on a toy example
The following illustrates the K-means algorithm on the 2D image shown Figure 2. The pixel intensities are drawn in a 2D space in Figure 3.
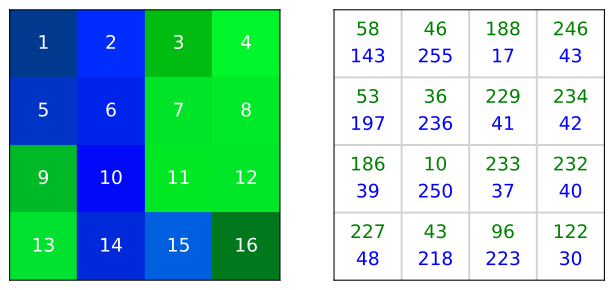
Figure 2:A 4×4 image with two bands. Suppose, for instance, that it is a remote sensing image showing a river flowing through a forest. Left: the image with bands in green and blue. Right: the image with the pixel intensities.
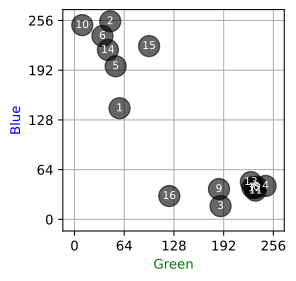
Figure 3:A 4×4 image with two bands. Suppose, for instance, that it is a remote sensing image showing a river flowing through a forest. Left: the image with bands in green and blue. Right: the image with the pixel intensities.
We start with the following iteration:
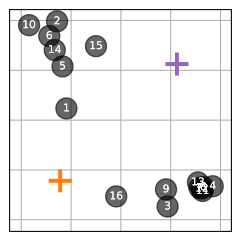
The 3 first iterations of the K-means algorithm are illustrated below. The black dashed line represents the frontier between the centroids.
| Iteration 1 STEP A Assign the pixels to the closest outlier 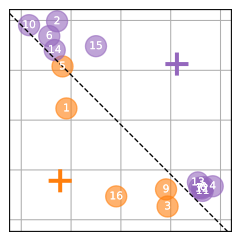 | Iteration 2 STEP B Update the centroid location 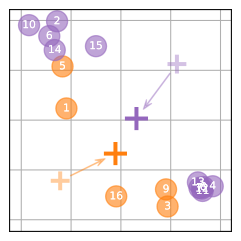 |
| Iteration 1 STEP A Assign the pixels to the closest outlier 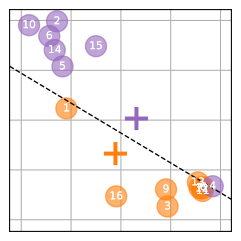 | Iteration 2 STEP B Update the centroid location 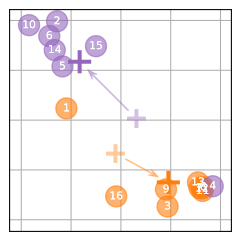 |
| Iteration 1 STEP A Assign the pixels to the closest outlier 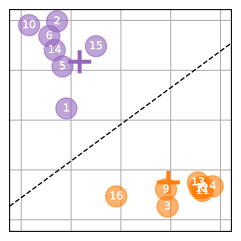 | Iteration 2 STEP B Update the centroid location 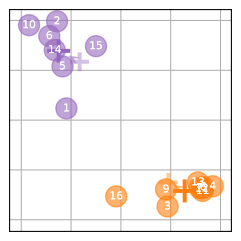 |
Application on a real image
Figure 4 gives the result of the K-means algorithm on an image.
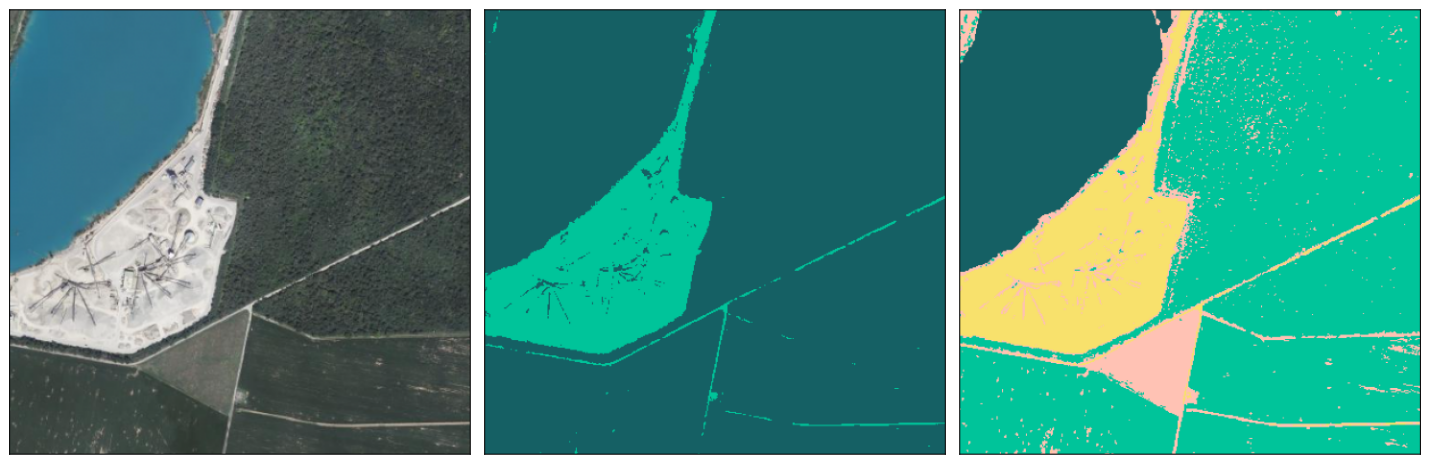
Figure 4:Segmentation of a real remote sensing image with the K-means algorithm. Left: observation, center: classes, right: classes. Especially, the segmentation with classes identifies water, forest, artificial areas and meadows.
Discussion
The pros and cons of the K-means method for image segmentation are listed below. In particular, the characteristics above identified with * are detailed hereafter. Other clustering methods are available to avoid some of limits, as for example Gaussian mixture modeling or mean-shift.
😀 Advantages of the K-means method
simplicity
easy to implement
generally fast
works correctly when the clusters are spherical*
☹️ Disadvantages of the K-means method
requires to know the number of classes
sensitive to initialization
can be slow in large dimensions
fails for non-spherical structures*
sensitive to outliers*
Spherical vs non-spherical clusters
Because the K-means algorithm performs the grouping with respect to the distance of the points to the centroids, it assumes that the clusters are spherical. Therefore, the algorithm works well for spherical clusters, but it fails if the clusters are not spherical, as depicted in the images below.
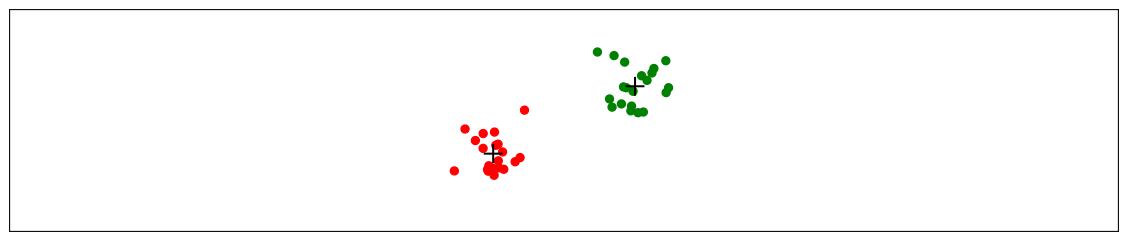
Figure 5:Spherical clusters: the K-means algorithm works well. The points are depicted by whose color correspond to the class, and the centroids are depicted by a black .
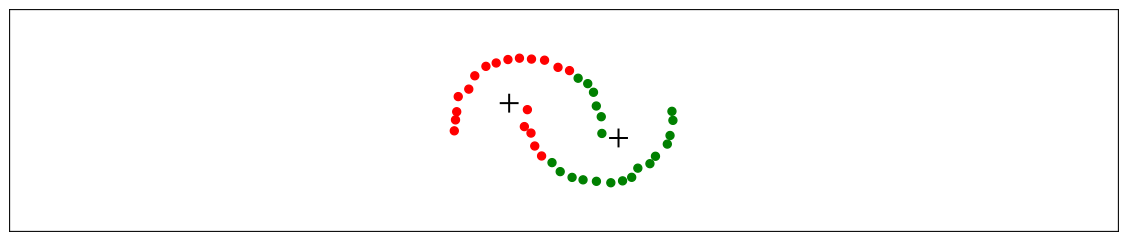
Figure 6:Non-spherical clusters: the K-means algorithm fails.
Sensitivity to outliers
In addition to this, the centroids are calculated as the mean of the points in the cluster. But the mean is not a robust estimation and is sensitive to points located far from the cluster. Thus, the algorithm may fail in the presence of outliers (valeurs aberrantes).
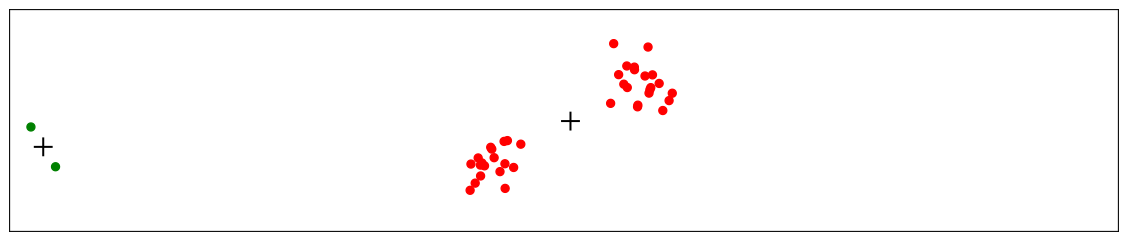
Figure 7:Presence of outliers: the K-means algorithm fails in this example.